

 Evaluations
The robot encoded the right instruction. Its hand still went elsewhere.
A new study separates information inside a policy from information that actually governs its actions.
The tests and evidence that separate a stronger model from a better-looking score.
Benchmarks · Reliability · Cost & performance
9 articles
EvaluationsA new study separates information inside a policy from information that actually governs its actions.
 Evaluations
Inspect Robots makes setup and termination programmable. Those unglamorous steps help determine what a performance score means.
 Evaluations
HumanoidToolBench separates recognising a useful tool from carrying, positioning and successfully using it.
 Evaluations
OpenViTac’s paired simulation and physical tasks make it possible to ask what tactile input contributes, rather than just whether it is present.
 Evaluations
Their contracting-workflow test shows why a better average score is not the same as a workflow a company can switch on. Mandatory rules need their own acceptance test.
 Evaluations
GDP.xlsx tests whether models find the evidence across a workbook before calculating. A missing sheet can matter more than another improvement in arithmetic.
 Evaluations
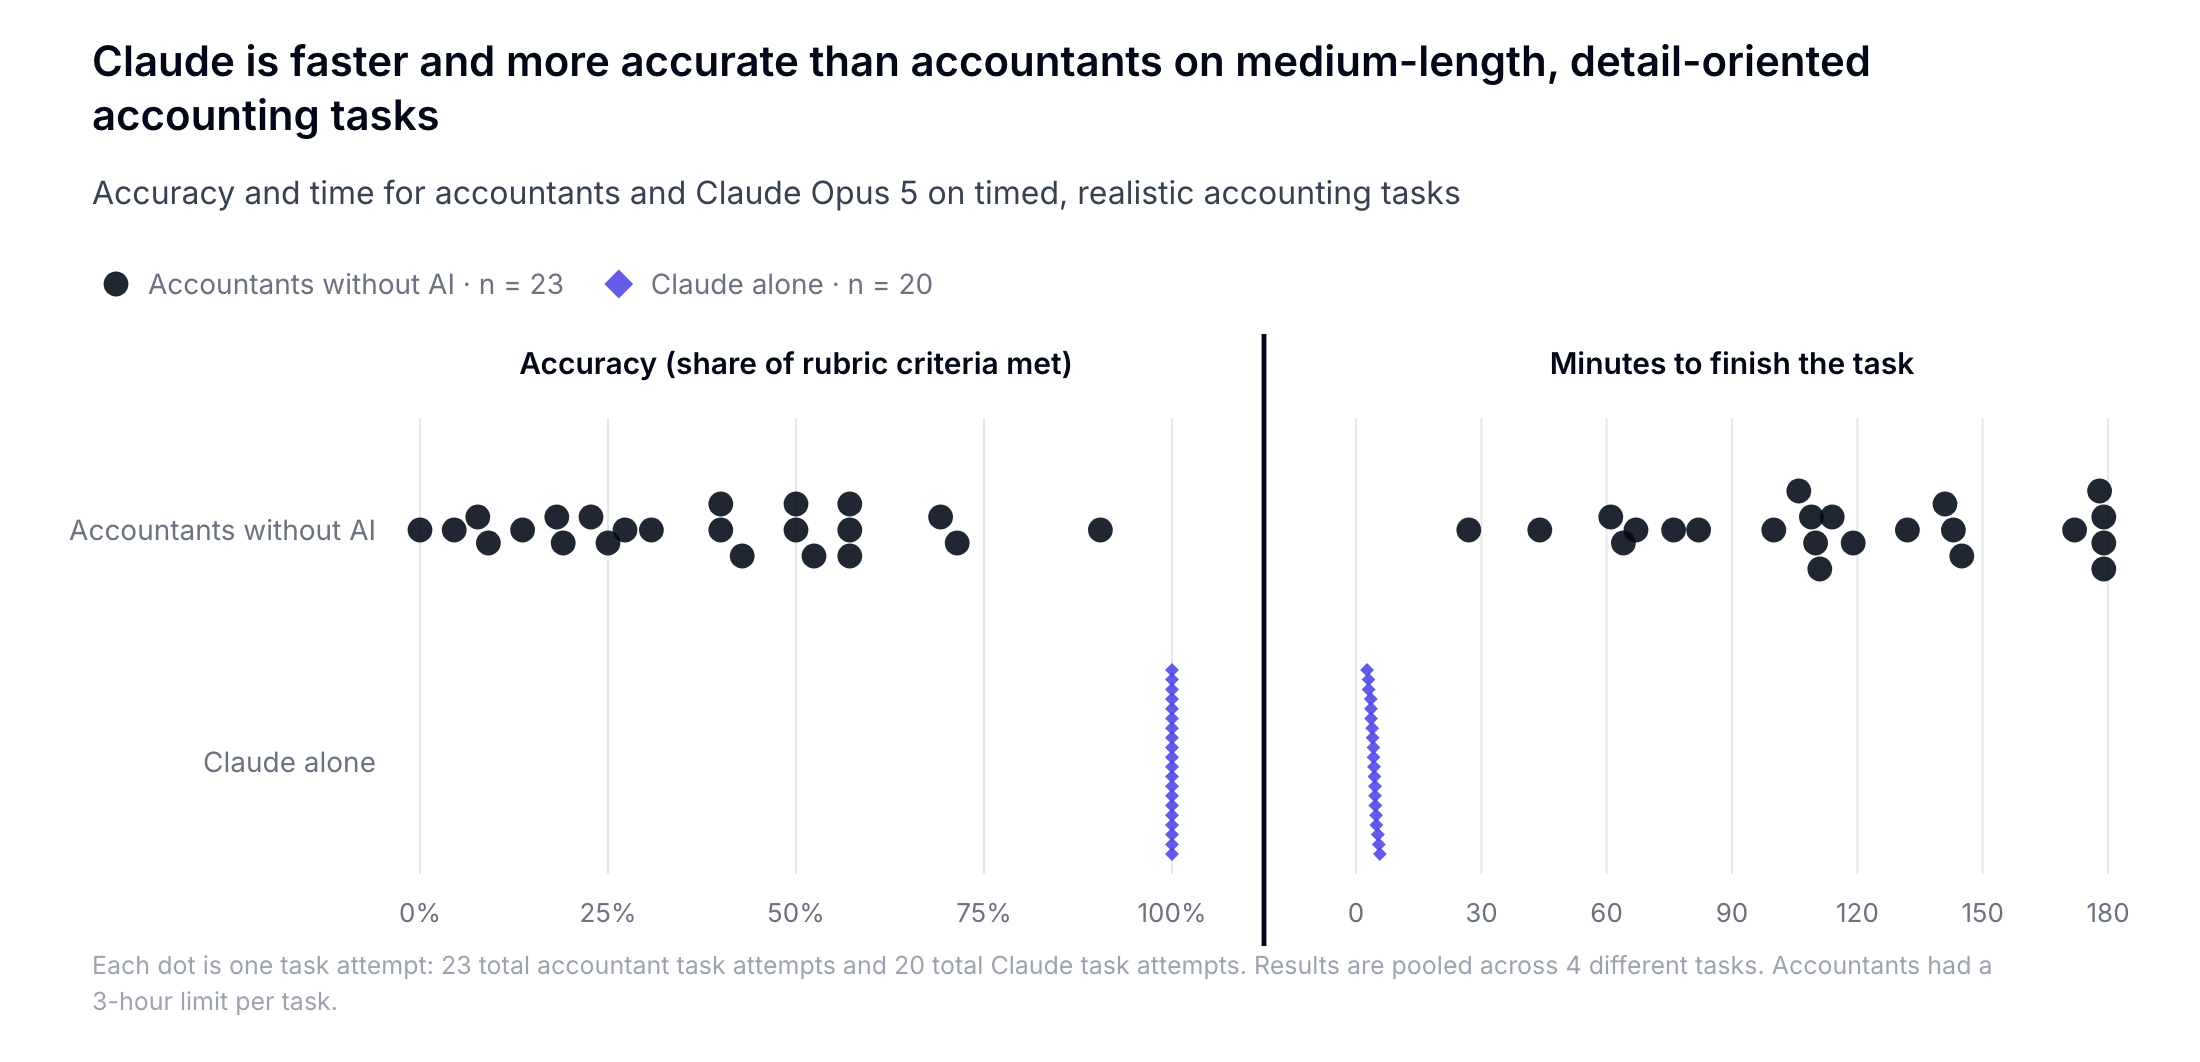
Its bounded comparison favors AI on structured tasks. The next question is whether that advantage survives ordinary workplace context, review and exceptions.
 Evaluations
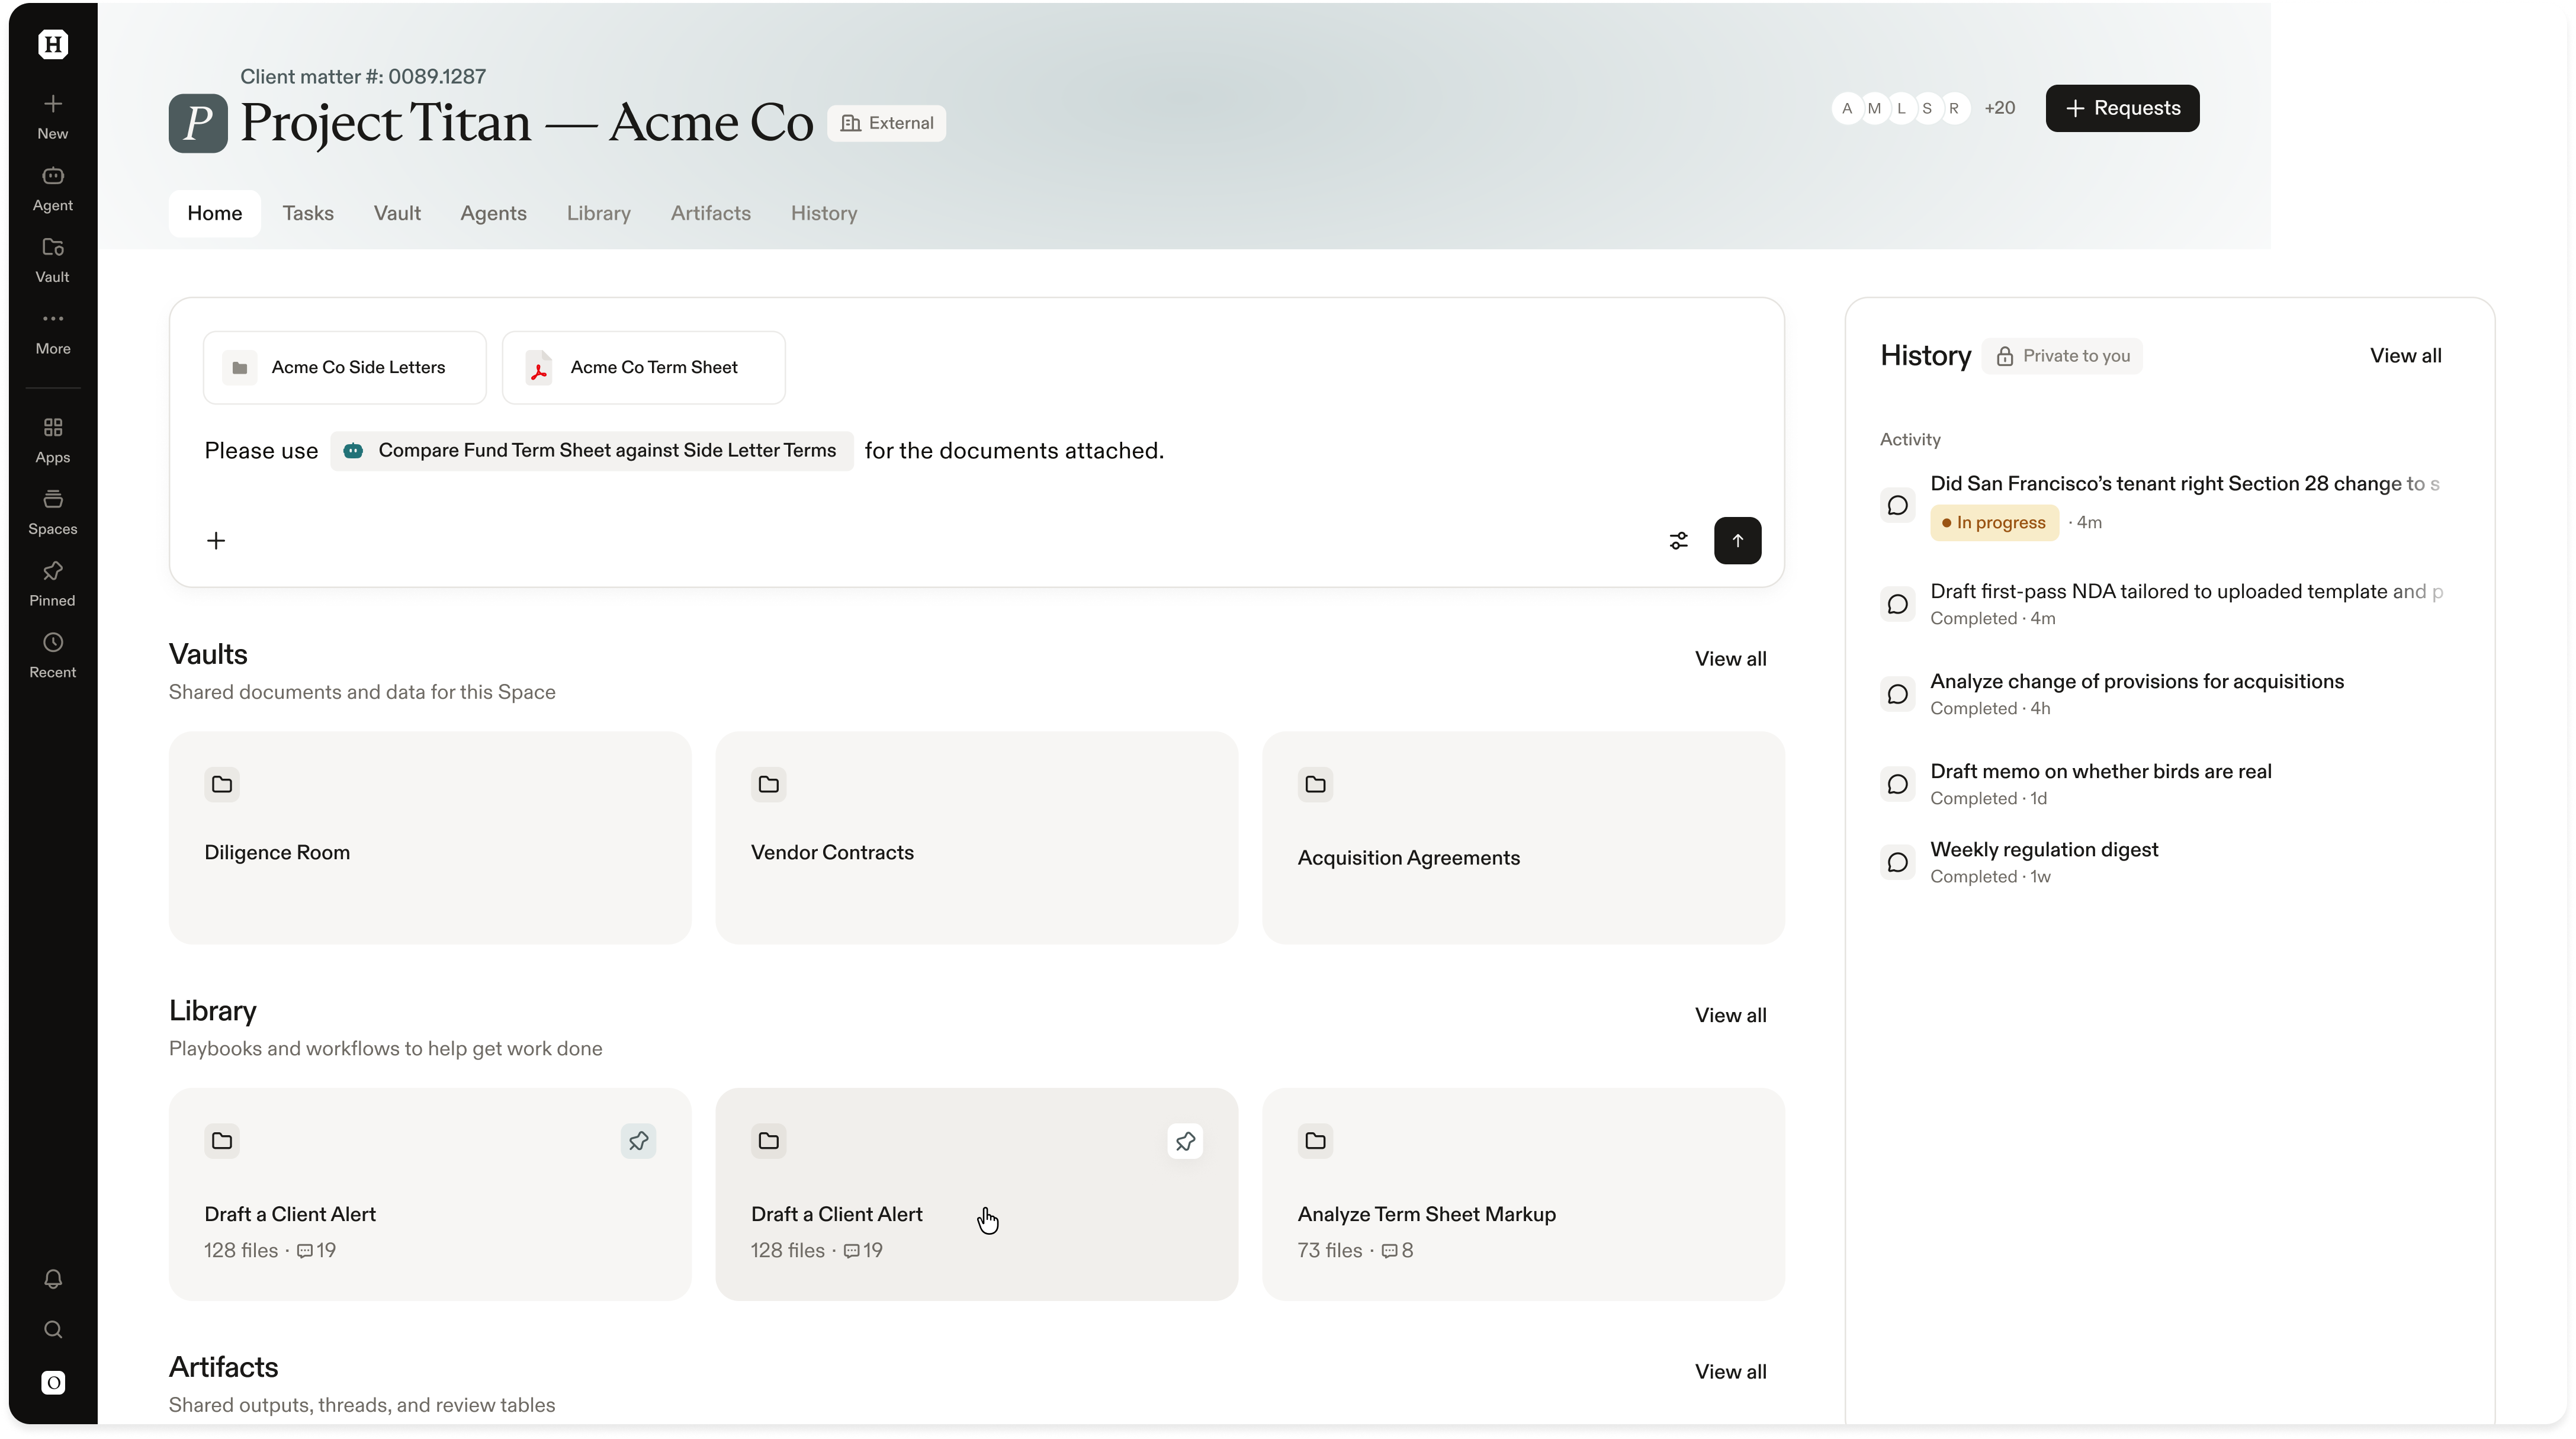
Artificial Analysis and Harvey now gate headline credit on grounded answers. That separates two problems model teams must solve: missing requirements and unsupported claims.
 Evaluations
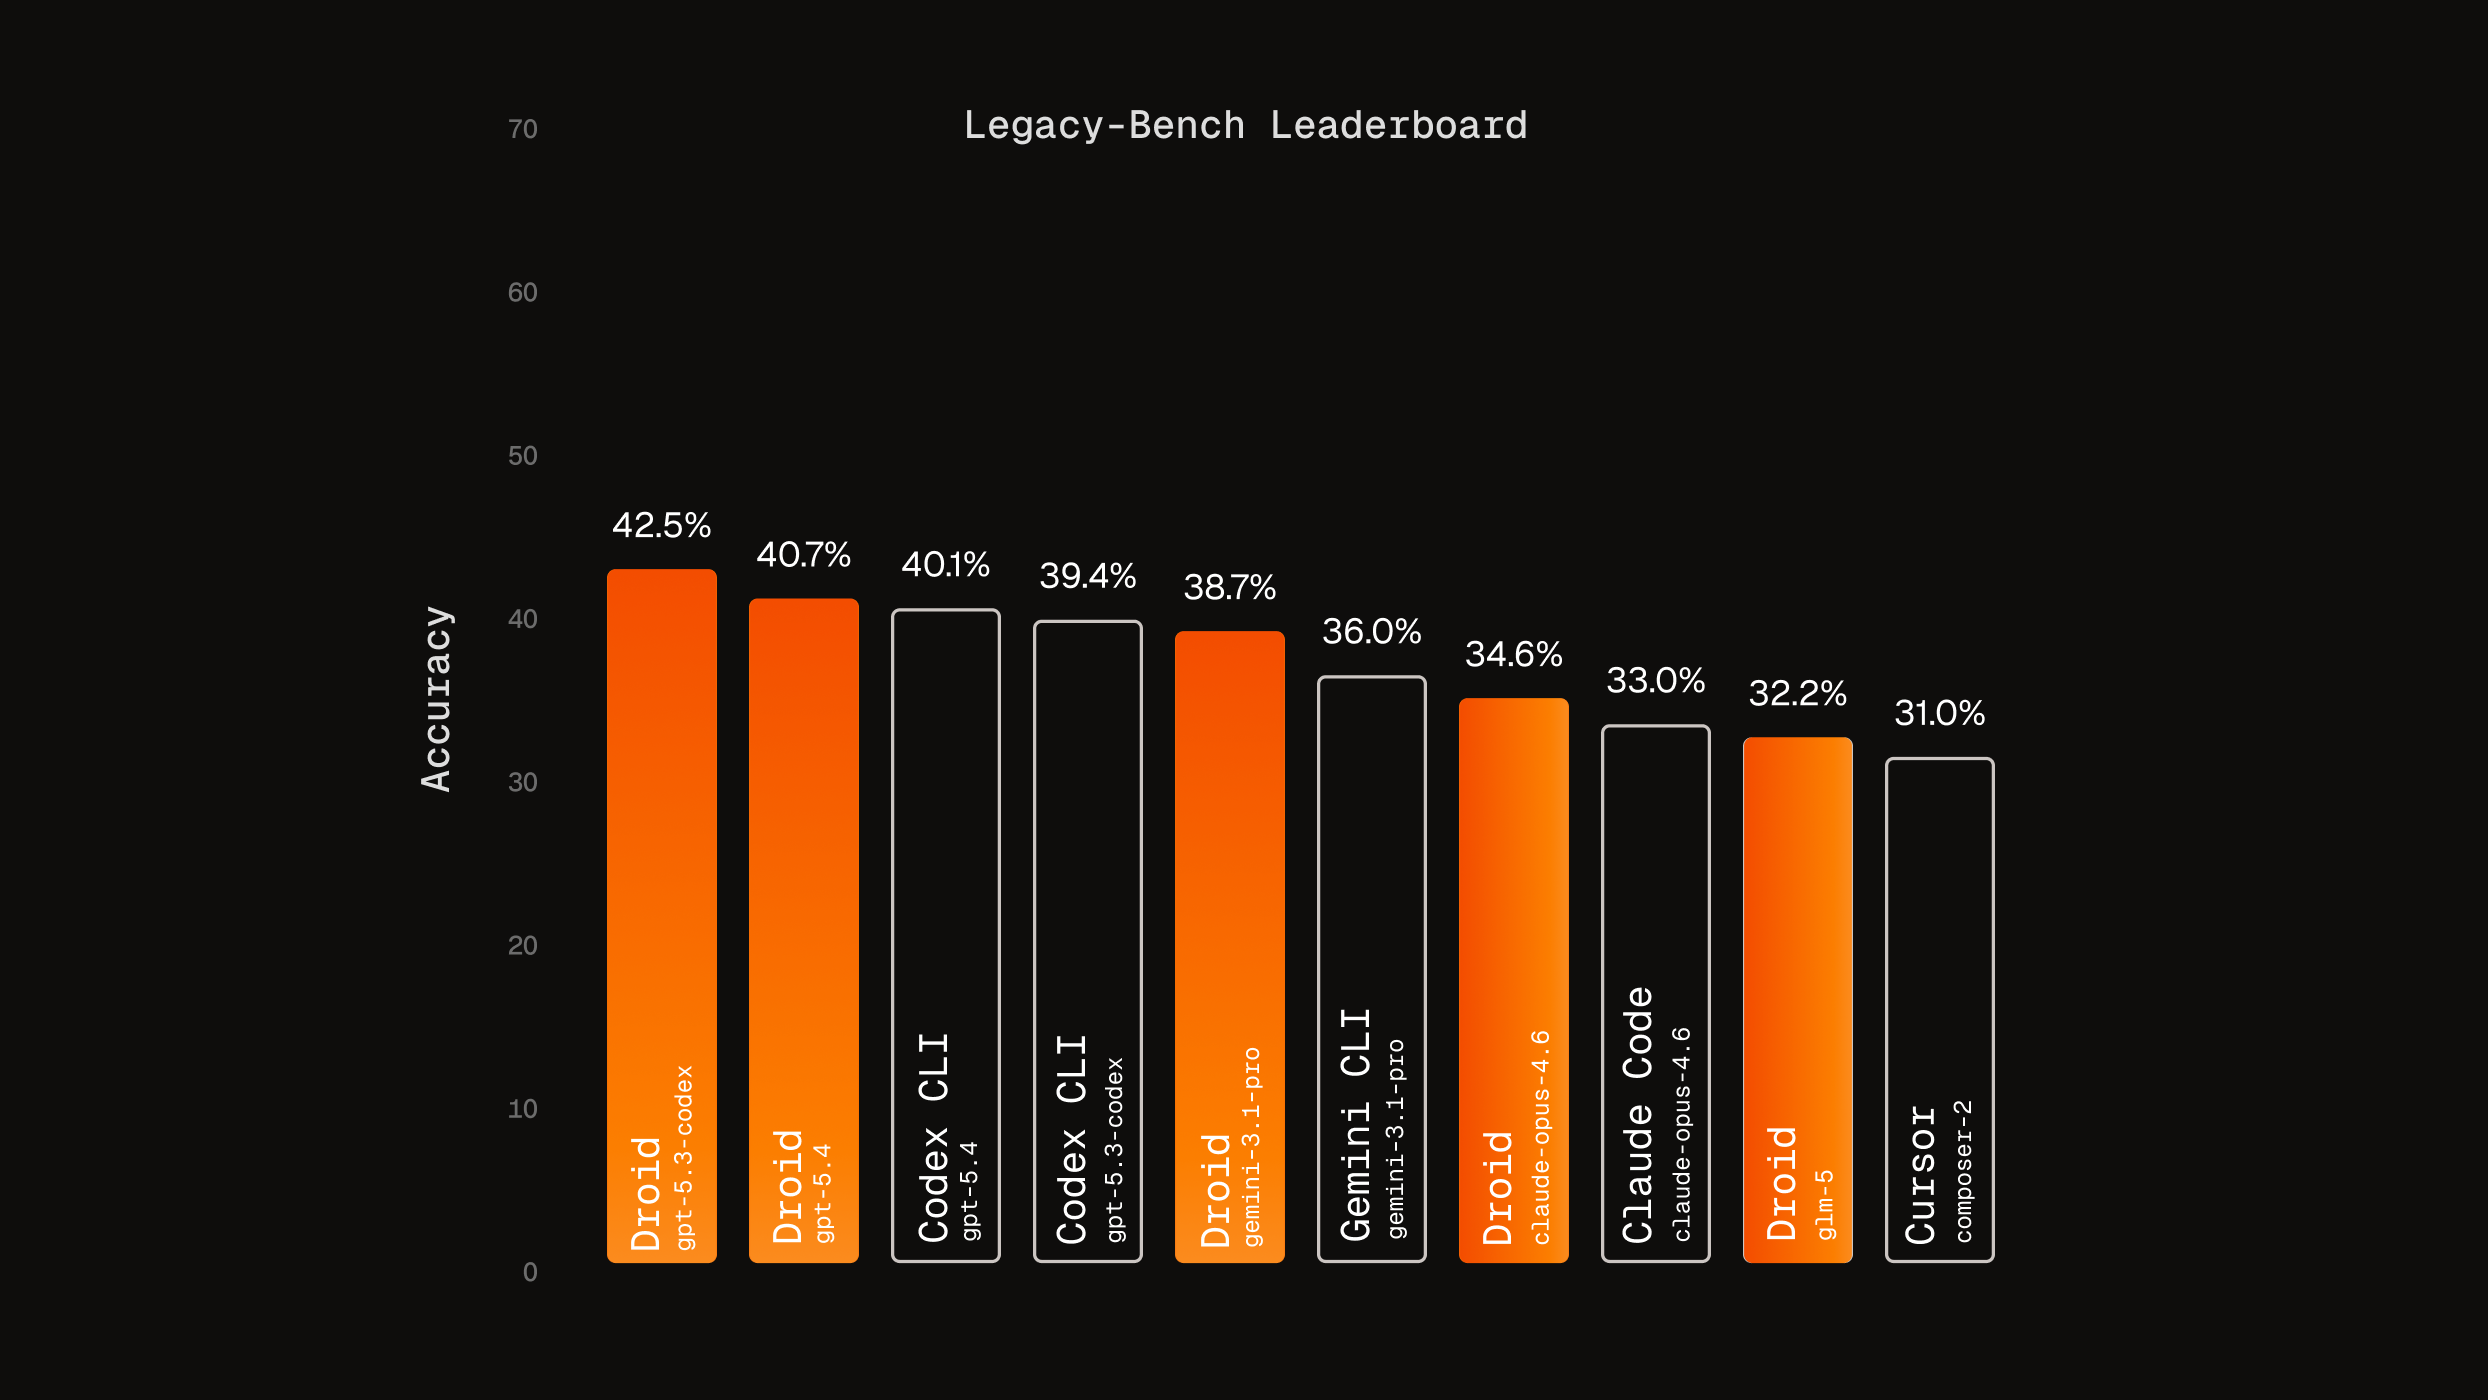
Legacy-Bench exposes a gap between an agent saying it is done and a repair passing independent checks. Preserved outputs and edge cases can matter as much as a stronger coding model.
Explore the other topics in this desk.