Subject desk / 4 articlesInference
How models reason and run: serving speed, memory, inference-time compute and cost per useful result.
Serving & runtime · Compression & efficiency · Inference-time reasoning
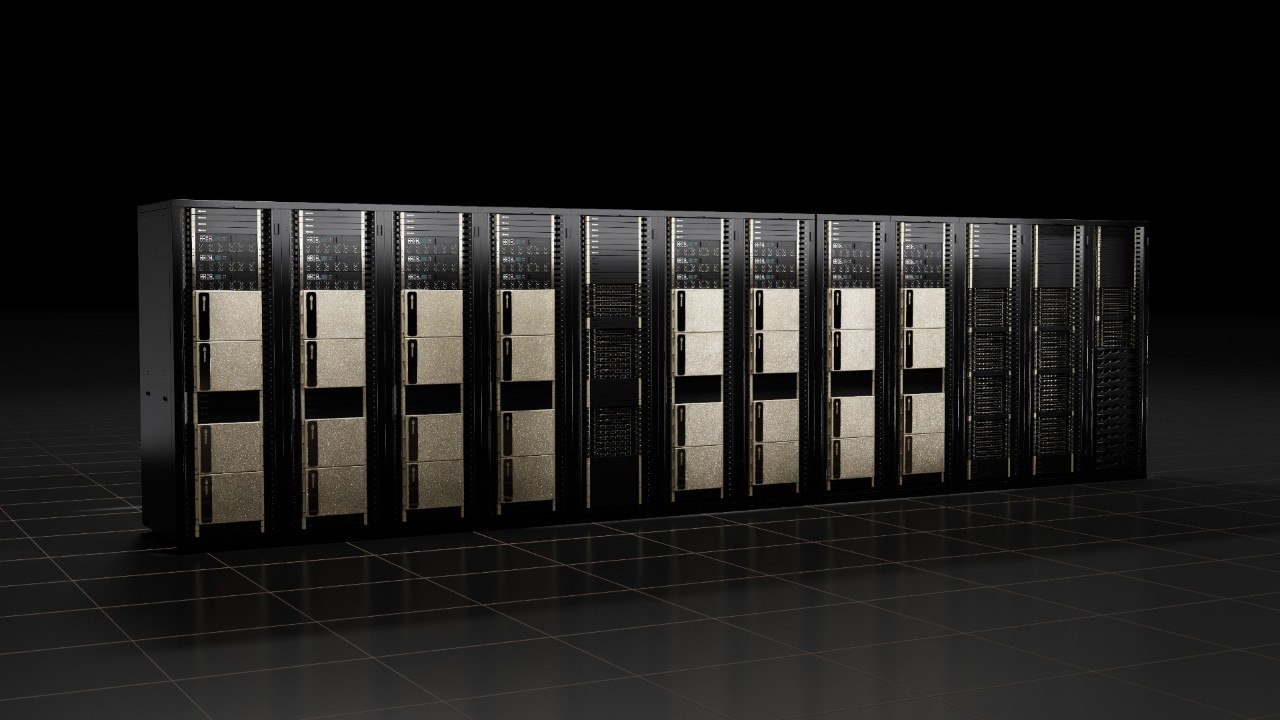 NVIDIA DGX SuperPOD infrastructure, shown as context for distributed inference. This is not a photograph of a specific vLLM deployment. Image: NVIDIA
4 articles
No articles in this topic yet
Explore the other topics in this desk.