

 Evaluations
AISI and EvalEval put the conditions behind benchmark scores into shared records
Configuration and inference budgets help explain why apparently comparable evaluations diverge.
The tests and evidence that separate a stronger model from a better-looking score.
Benchmarks · Reliability · Cost & performance
10 articles
EvaluationsConfiguration and inference budgets help explain why apparently comparable evaluations diverge.
 Evaluations
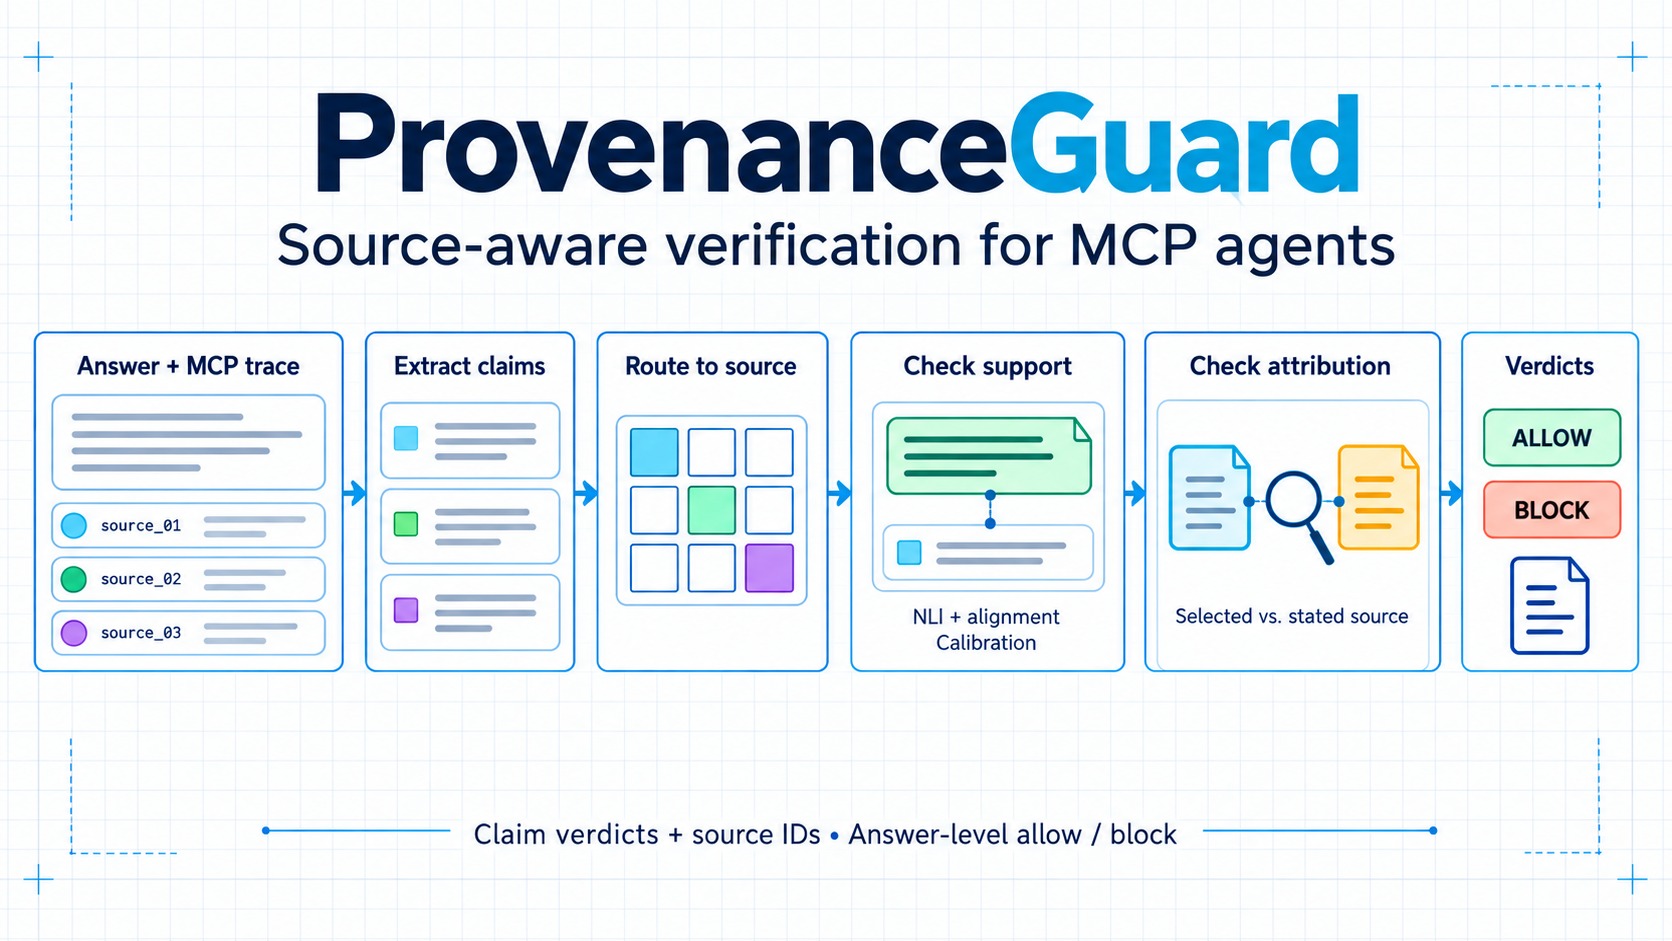
The study separates pooled factual support from source attribution, while showing the cost of conservative blocking.
 Evaluations
Six embedded evaluators receive employee-like access, while predefined exclusions and redaction authority remain important limits on what independent oversight can reveal.
 Evaluations
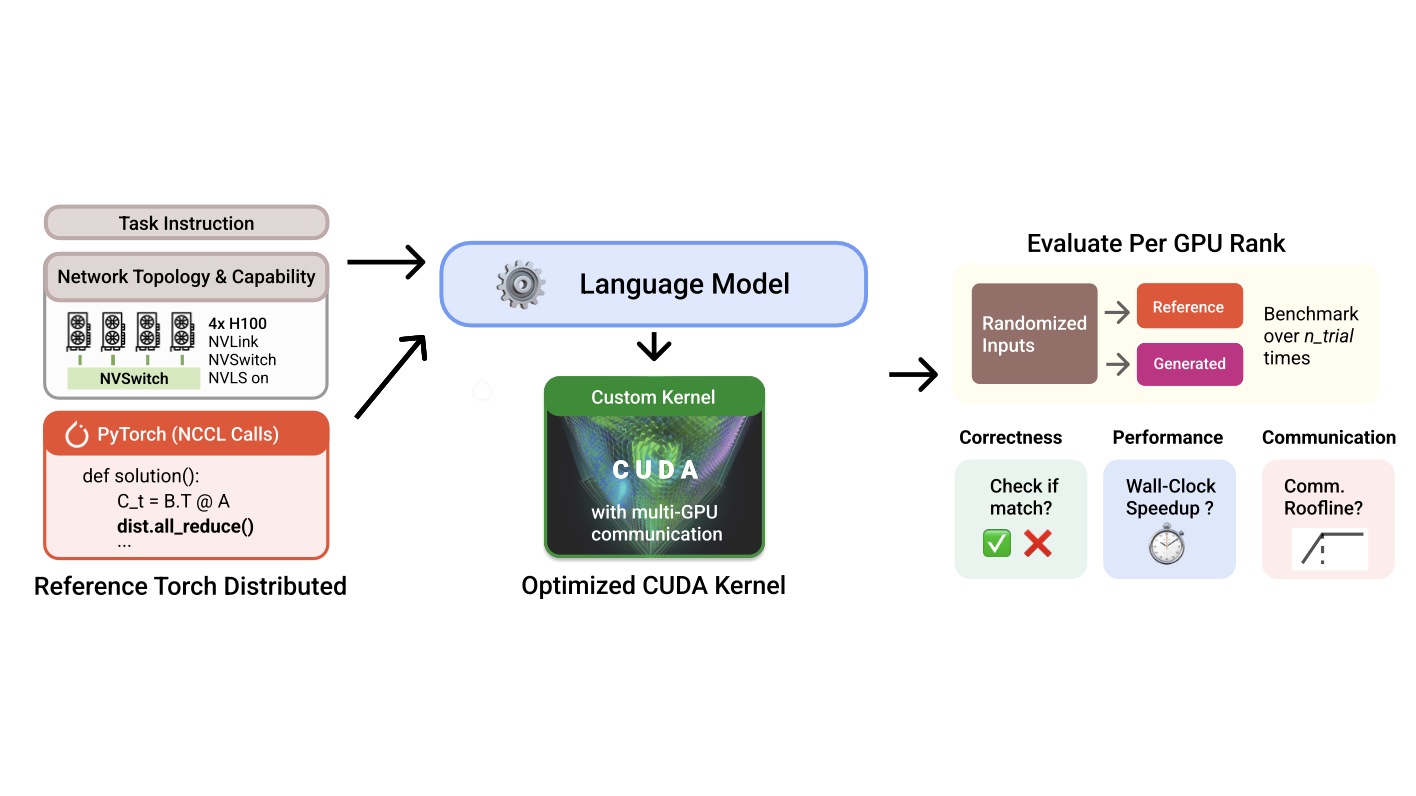
The June benchmark separates kernels that run correctly from kernels that also beat a reference implementation, exposing the communication work that single-device tests miss.
 Hover to animateEvaluations
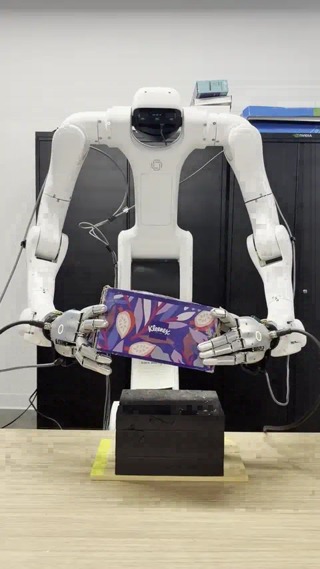
The released workflow reaches GR00T N1.7 training. A small real-robot test shows why simulated practice and real adaptation need to be examined separately.
 Hover to animateEvaluations
Their contracting-workflow test shows why a better average score is not the same as a workflow a company can switch on. Mandatory rules need their own acceptance test.
 Hover to animateEvaluations
GDP.xlsx tests whether models find the evidence across a workbook before calculating. A missing sheet can matter more than another improvement in arithmetic.
 Hover to animateEvaluations
Its bounded comparison favors AI on structured tasks. The next question is whether that advantage survives ordinary workplace context, review and exceptions.
 Hover to animateEvaluations
Artificial Analysis and Harvey now gate headline credit on grounded answers. That separates two problems model teams must solve: missing requirements and unsupported claims.
 Hover to animateEvaluations
Legacy-Bench exposes a gap between an agent saying it is done and a repair passing independent checks. Preserved outputs and edge cases can matter as much as a stronger coding model.
Explore the other topics in this desk.
Explore the research library for paper-based analysis.