

 Inference
Liquid AI’s LFM2.5 puts local agent performance under a workload-specific test
Sparse activation lowers per-token work, while total memory and completed-task cost still govern deployment.
How models reason and run: serving speed, memory, inference-time compute and cost per useful result.
Serving & runtime · Compression & efficiency · Inference-time reasoning
10 articles
InferenceSparse activation lowers per-token work, while total memory and completed-task cost still govern deployment.
 Inference
The reported gains concern constrained experiments; the engines were not serving production traffic in the October account.
 Inference
Together AI's October update describes an IBM Cloud-NVIDIA collaboration; IBM's original agreement sets a Q1 2027 availability expectation, so capacity plans must remain distinct from a generally available service.
 Inference
A March research release separates cold prompts from cache-backed requests; its reported throughput gains apply to a specified mixed workload, not every inference service.
 Hover to animateInference
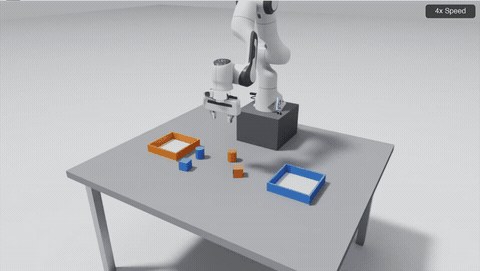
Liquid AI’s d1 measurements suggest several decisions can share the cost of reading a scene. The saving depends on how quickly that scene changes.
 Hover to animateInference
QVAC’s new on-device recogniser makes the distinction between bulk throughput, short-utterance latency and first-load cost unusually visible.
 Hover to animateInference
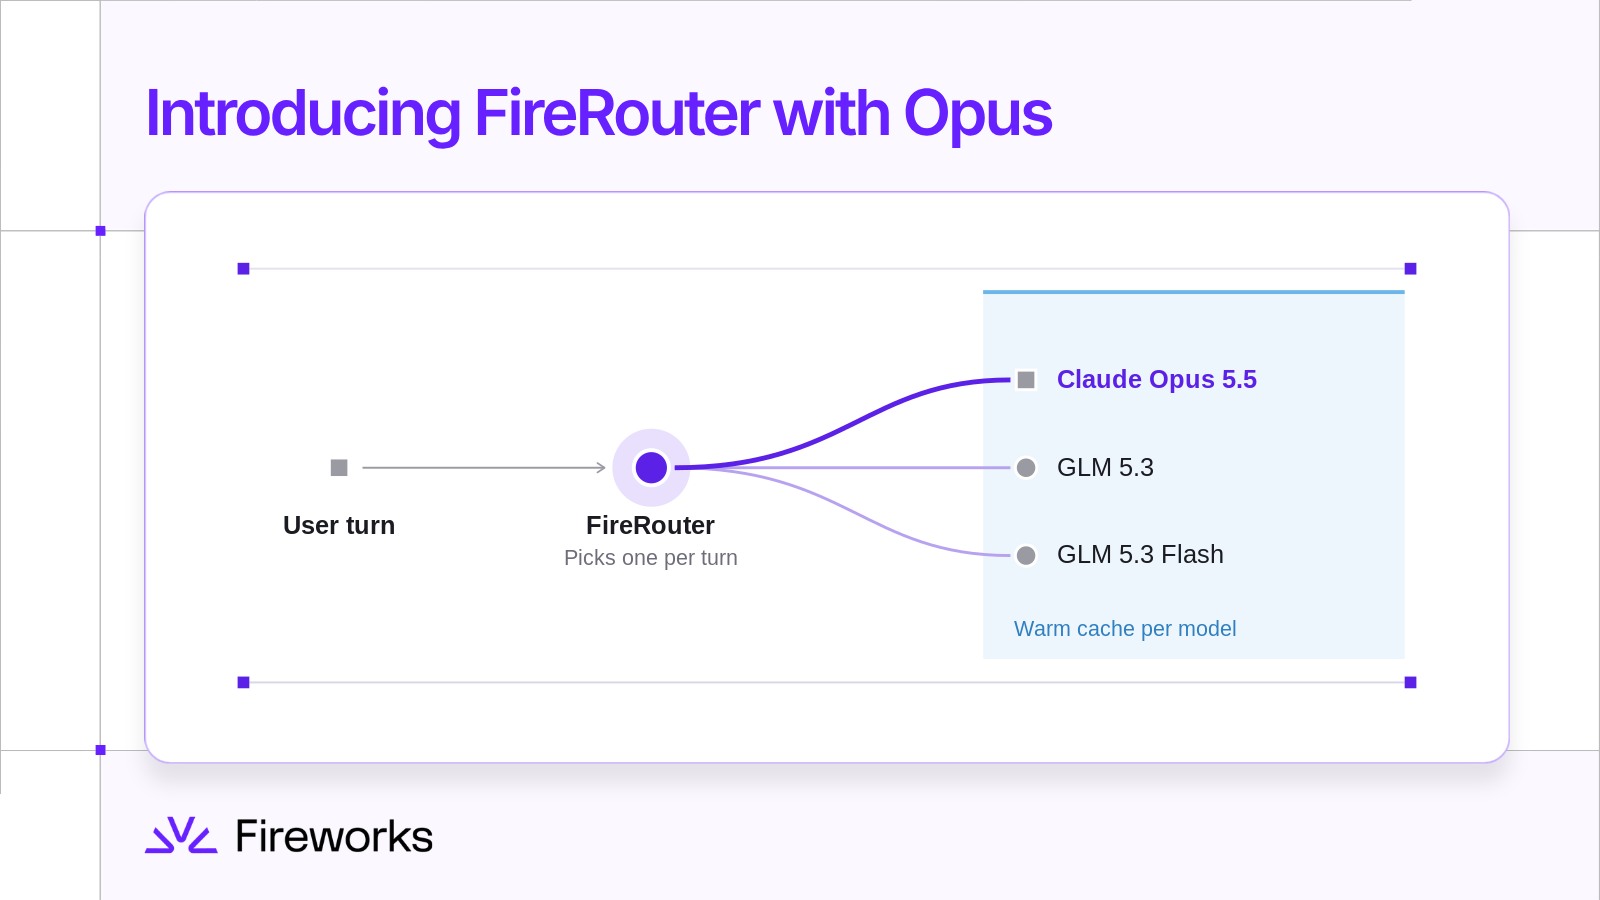
Fireworks’ new router weighs the price of switching models against the cached work a session would lose. Its internal test shows substantial savings with a modest accuracy trade-off.
 Hover to animateInference
Agentic Search gives models tools to inspect documents after finding them. Company tests suggest those extra capabilities can replace costly repeated searches.
 Hover to animateInference
A small model proposes several tokens at once; the main model checks them. Better accepted guesses can reduce expensive model passes without handing the final answer to the smaller model.
 Hover to animateInference
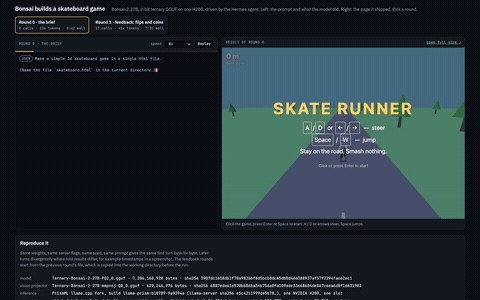
Bonsai 2’s reported 5.9 GB footprint raises a deployment question: can the compressed model meet your task standard locally, after context memory and fallback costs are included?
Explore the other topics in this desk.
Explore the research library for paper-based analysis.