A saved procedure can replace many reasoning steps with one lookup. Its long record of success can also make it stubborn after the underlying facts change.
An October 13 paper calls this reasoning contraction and studies counters used to judge memory reliability. Under its assumptions and experiments, accumulated successes can delay recognition of partial changes. The proposed certification process compares reuse with live reasoning and resets evidence when conditions change. Read the research paper.
A shortcut changes the system's relationship with evidence
Thought templates, cached answers and skill libraries turn repeated reasoning into reuse. Their value is clear when the underlying world remains stable: the system saves work and avoids some errors associated with solving the same problem again. But reuse also removes opportunities to notice that a fact, API or prerequisite has changed. A shortcut can retain the appearance of well-earned reliability after the conditions supporting it disappear.
The paper calls this process reasoning contraction. It studies not only whether contraction saves work, but how a system can certify that the saved reasoning remains safe to skip.
A long success history can be a bad change detector
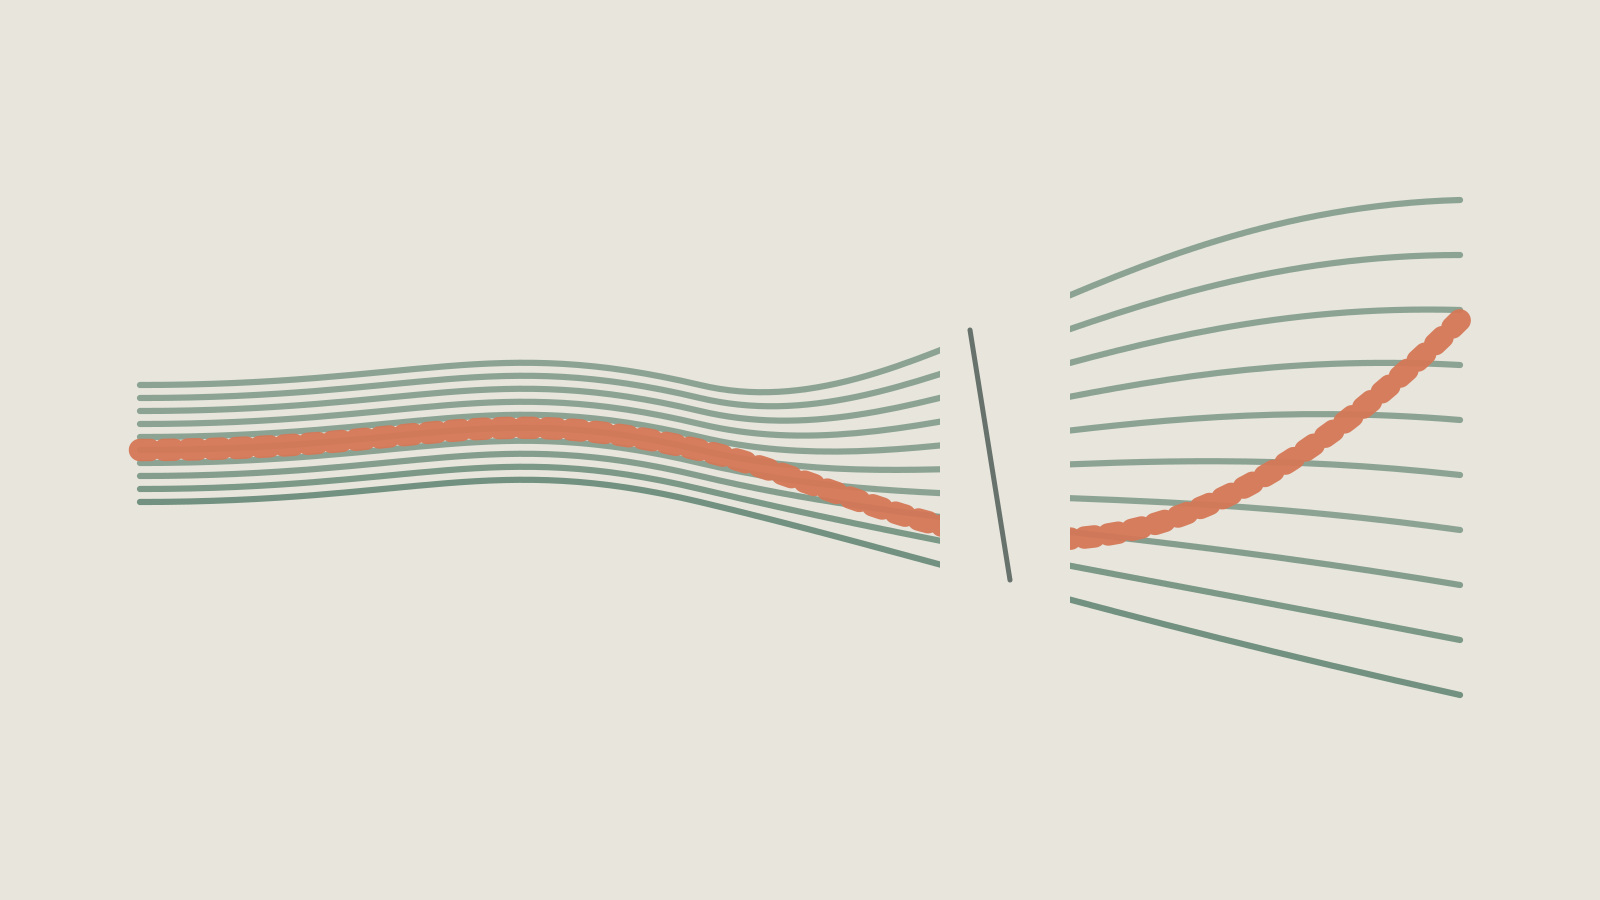
Many memory systems count successes and failures to decide whether a stored procedure deserves trust. Under the paper's assumptions, those counters can react poorly to partial changes. Earlier successes may overwhelm new evidence of failure; an unclipped counter can in some conditions fail to detect the change at all. The issue is not that the past outcomes were wrong. They answer a historical question that differs from present validity.
The authors propose weighing failures by a memory-specific likelihood ratio, certifying utility against live reasoning and restarting certification when facts change. A detector provides a safeguard for unannounced changes, while large edits can trigger invalidation.
Stale answers become the meaningful outcome
Across five language models on multi-hop questions with edited facts, the authors report that ExpeL- and ACE-style counters serve 7.0 to 13.5 times more stale answers than certified memories given the same information. On code tasks with an exact verifier, the reported difference is thirty-five to seventy-three times. These ratios belong to the paper's controlled experiments; they are not forecasts for every production memory system.
Their importance is the choice of measurement. Cache hit rate rewards reuse regardless of whether it is still justified. Counting stale answers after a change directly measures the harm created when yesterday's valid contraction persists into today's environment.
Exact verification defines the present boundary
The experiments concern memories whose outputs can be checked by exact verifiers, such as knowledge-base execution and unit tests. The evidence spans controlled knowledge-graph edits, a natural timeline of Wikidata qualifiers and code tasks with revised requirements or re-enacted API changes. Five open models of up to eight billion parameters are included.
This matters for open-ended agents, where the verifier itself may be uncertain. A statistical certificate built on exact outcome checks cannot simply be imported into a setting with ambiguous quality labels. The theoretical assumptions also specify how changes and audit outcomes arise. The practical warning about stale shortcuts travels widely; the formal safety result travels only with the assumptions that make its evidence reliable.
Fresh confidence cannot be obtained for free
Certification requires evidence, and evidence can require live reasoning or verification. The paper analyses a certification load that limits how much work a safe memory can avoid under its setting. This identifies a real tension: reducing reasoning also reduces the observations that could reveal a failing shortcut. A claim of nearly free reuse should therefore explain how its validity is refreshed.
For agent developers, attach explicit assumptions and change signals to reusable procedures where possible. Then test both announced and unannounced changes. A memory that is allowed to forget at the right moment may be more useful than one with a larger library and a better historical success rate. Durability should belong to the validity check as well as to the stored skill.
Questions, news tips or corrections? Contact [email protected].