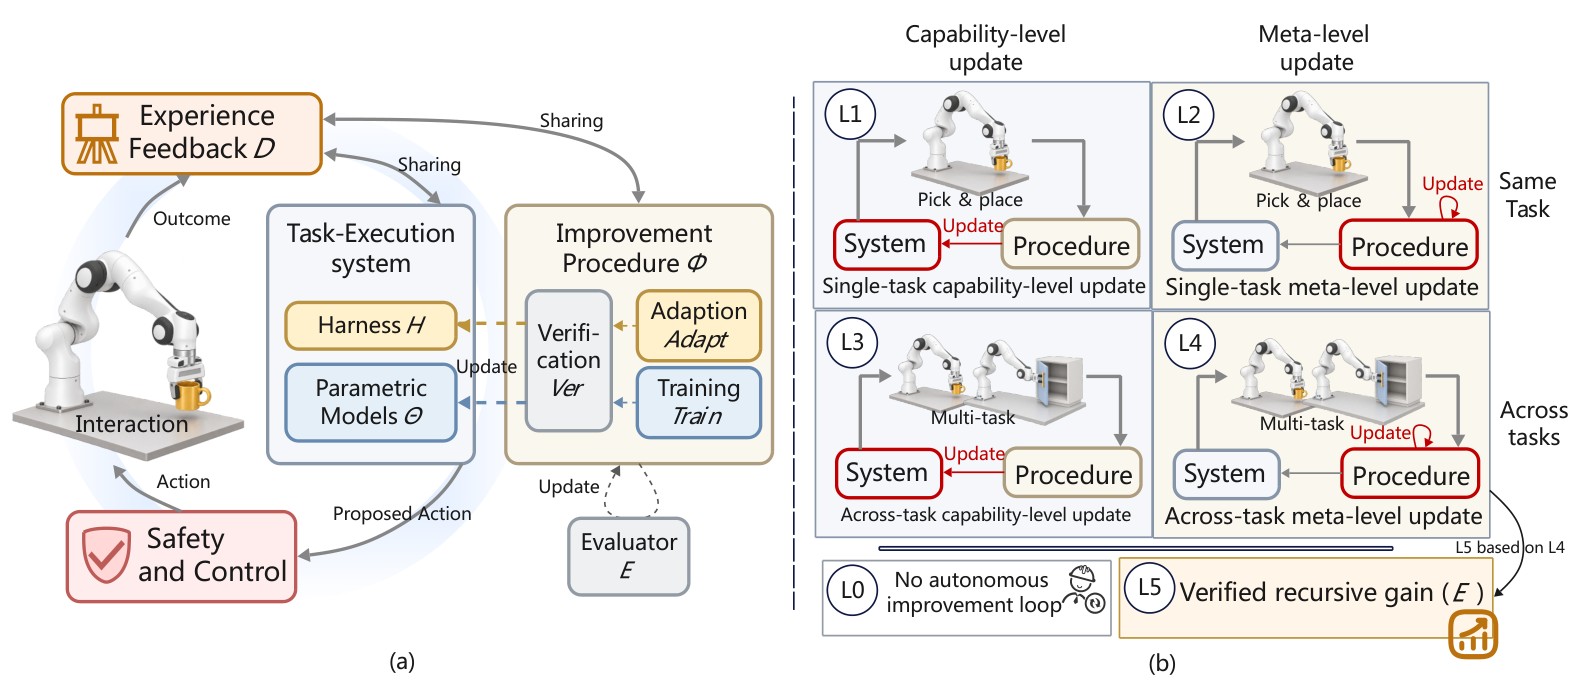
An agent working for hours may receive no useful reward until the final artifact is checked. A failed run then reveals little about which earlier decision went wrong.
Tev's October 13 paper constructs agent environments from hidden specifications of workflows and intermediate states. A progress-based reward-shaping recipe supplies denser feedback, and the authors report training gains on long-horizon tasks. Read the research paper.
The environment supplies the missing measurement
The contribution is not simply a more generous reward. A known task specification lets the system measure meaningful progress. Without that grounding, an agent could earn apparent progress by producing persuasive intermediate activity.
Synthetic environments with complete specifications are also easier to verify than many real professional tasks. Transfer tests matter because real workflows contain missing information, ambiguous goals and changing dependencies.
For training teams, inspect whether intermediate rewards preserve the original objective. A locally rewarding step can still lead away from a successful final result if the progress measure is misspecified.
Tev shows why environment design belongs in discussions of model improvement. Some long-horizon failures reflect weak learning signals rather than an intrinsically incapable backbone. Making progress observable can unlock training, provided the observable progress remains connected to the actual job.
References
Questions, news tips or corrections? Contact [email protected].